LLM Inspector
The LLM Inspector view provides administrators with a detailed, low-level view of the exchanges between the AI Support system and the language model. This tool is essential for debugging assistant behavior, verifying that the correct context is being sent to the model, and understanding why the AI generated a particular response.
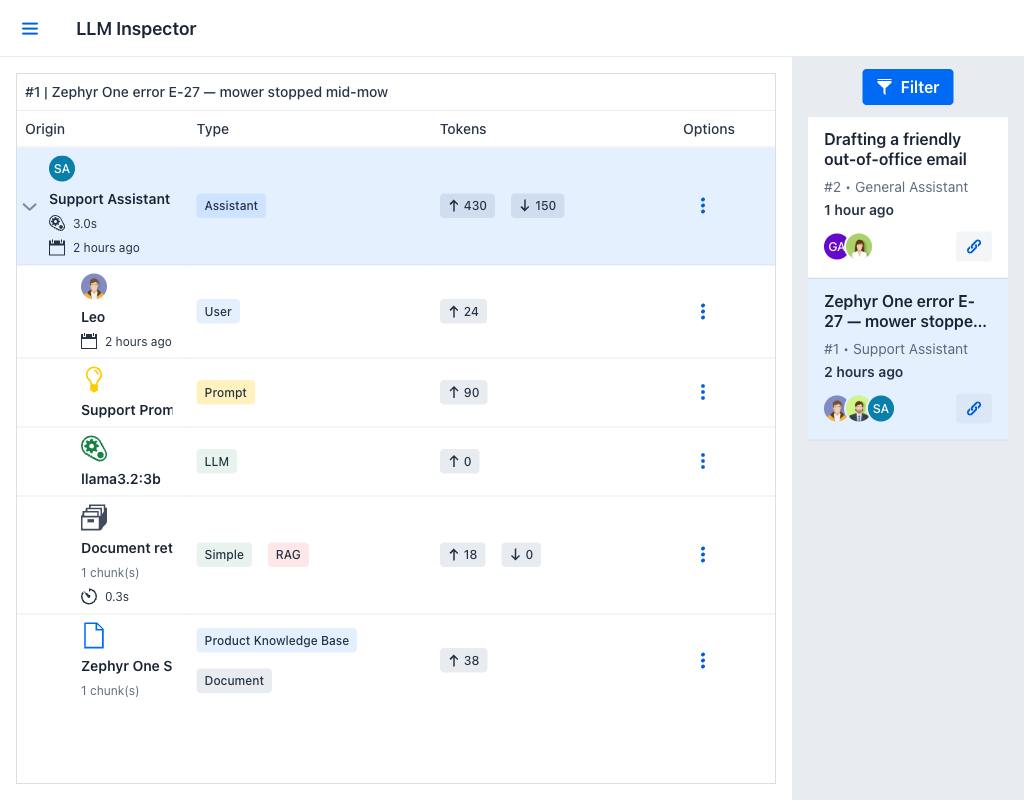
Layout
The LLM Inspector uses a two-panel layout. The left panel displays the exchanges of the selected session as a tree. The right panel displays the list of sessions available for inspection. The Sessions button in the header of the left panel hides the session list to leave more room for the exchanges, and shows it again.
When no session is selected, the left panel displays Select a session to continue.
On a phone the two panels are shown one at a time. The session list fills the screen, tapping a session opens its exchanges, and the Sessions button returns to the list. The phone's Back also returns to the list, even when the session was opened from a link.
Session Selection
The session list on the right side displays sessions as cards, with their summary, number, assistant name, last activity time, participants, and rating. The Filters button opens the same Session filters dialog as the Chat view, described in Session filters. Each card also offers Copy session link.
Clicking a session loads its exchanges into the left panel, and the panel header shows the session number and summary. A session in which no assistant has answered yet reports that no messages made by assistants were found.
The Exchange Tree
The left panel is a tree grid with four columns:
- Origin: What produced the entry — an assistant, a user, a prompt, a language model, or a document — with its name and timestamp.
- Type: One or more badges classifying the entry.
- Tokens: The token counts, shown as an inbound and an outbound value where both apply. A count that cannot be estimated reads Unknown, as it always does for Anthropic and Gemini models, for which no tokenizer is available. A newer OpenAI model is estimated as the GPT-4o and GPT-5 models are, and a message without text, such as a voice note sent alone, counts as zero.
- Options: A per-row actions menu.
Each top-level row is one exchange: a single request-response cycle with the language model, labelled with the assistant that answered and the time the request took. Expanding it reveals everything that went into that request, each part as its own row:
- User: The message that triggered the exchange.
- Prompt: The system prompt in force at the time.
- LLM: The language model that was called, titled by its type — OpenAI, Ollama, Anthropic, or Gemini — with its name as content. Its connection settings are not part of the record.
- Tools: Present when the assistant had tools assigned at the time, with the tokens the tools cost. See Tool Usage.
- Document retrieval: Present when RAG ran, with the number of chunks retrieved and how long retrieval took.
- Document: One row per retrieved document, with its categories.
This structure makes it possible to trace exactly how a user message was processed: what context was assembled, what was sent to the model, and what came back.
The Type badges are worth reading closely. Simple and Advanced distinguish standard retrieval from advanced RAG with query expansion. RAG marks the retrieval step itself. Private marks an administrator-only message. Attachments marks files submitted with a message. Tools marks the tools row, and the assistant's answer when the model called at least one tool. Early marks a response whose generation was stopped before it finished, and Failed marks one that could not be generated.
Row Actions
The actions available on a row depend on what the row represents:
- Request: On an exchange row, opens the full request that was sent to the model.
- Content: On the other rows, opens the content that row contributed — the user's message, the prompt text, or a document's retrieved text.
- Response: Opens the full response received from the model. When the request failed, the response includes an Error entry with the reason the provider gave, next to the partial answer if there was one. Credentials such as API keys are removed from it before it is recorded.
- Retrieved documents: Opens the retrieval detail described below.
- Retrieval queries: Opens the same dialog on its queries section.
- Definitions: On the tools row, opens the tool definitions sent to the model, one entry per tool. It is hidden when no definition was sent.
- Tool calls: On the tools row, opens the tool usage dialog described in Tool Usage.
- Go to conversation: Navigates to the message in the Chat view, which is the quickest way to see an exchange in the context the user experienced.
Content opens in a dialog that names its source, such as Request to, Response from, or Content from, and renders markdown. Long values can be sorted oldest or newest first, and report their token and character counts. An item without any text reads This content is empty.
When an exchange predates the audit record, or its record has been pruned, the inspector reports that the complete exchange data for the message is unavailable rather than showing an empty dialog.
Message Attachments
When a user message includes file attachments, they are marked with an Attachments badge and listed with the message, so administrators can see exactly which files were submitted as part of the conversation turn being inspected.
Tool Usage
The Tools row reports what the tools of an exchange cost. Its inbound tokens cover the definition of every tool, which travels in every model call of the exchange, plus each tool result, which travels in every call after it. Its outbound tokens are the model's requests to call the tools. When a response also held text for the user, and no tokenizer is configured for the model to tell the two apart, the outbound count is shown as an upper bound, such as ≤ 120. A count that cannot be estimated at all reads as Unknown.
The Tool calls action opens the Tool usage of dialog, named after the assistant. It opens with the number of model calls the request took, which is what the token counts multiply by, and lists the tools as a tree with the following columns:
- Tool: The tool name with the number of times it was called; expanding it lists each call as Call #1, Call #2, and so on.
- Details: The tool description, or for a call, the result it returned.
- Tokens: The inbound and outbound tokens of the tool or the call. The tooltip of a tool breaks the inbound count into its definition, over the number of model calls, and its results.
- Duration: How long a call took.
- Status: Used or Not used for a tool, or how many of its calls failed; Succeeded or Failed for a call.
- Actions: On a call, the Arguments and result button opens what the model sent to the tool and what the tool returned, in a dialog titled after the call, such as Call #1 to orderStatus. A Go back button returns to the tool usage dialog.
Used tools come first, the most called at the top, followed by the tools that were offered and never called, and then the assigned tools that were Unavailable when the request was made. A tool that was never called still shows what its definition cost, which is what to look at when deciding which tools to unassign from an assistant. Search tools and Only used narrow the tree.
When every tool assigned to the assistant was unavailable, no definition was sent, and the tools row says so instead of listing definitions.
Document Retrieval Detail
The Retrieved documents and Retrieval queries actions open the Document retrieval dialog, which explains why the assistant was given the context it was given. It reports the Search type — simple or advanced RAG — and two timings: RAG time for the whole retrieval, and Query time for generating the expanded queries when advanced RAG is in use.
The dialog has two sections:
- RAG Queries lists the queries that were actually run against the embedding store. With standard retrieval this is the user's message; with advanced RAG it is the set of reformulations generated from it, each numbered and scored. Filter grid by this query narrows the chunks below to the ones a single query returned. A session with no recorded queries reports that none were found.
- Retrieved Chunks lists the chunks that came back, with the columns Document, Index, Content, and Metadata, and a total count. Filter by query and Filter by document narrow the list.
Opening a chunk's Metadata shows the score it achieved, the document and chunk index it came from, and its category information. Document nodes also report an Average score across their chunks.
Read together, these two sections answer the question a poor answer usually raises: whether the right passages were retrieved at all, or whether they were retrieved and the model failed to use them.
Use Cases
The LLM Inspector is valuable in several scenarios:
Quality assurance: After configuring a new assistant or updating a prompt, administrators can review the inspector to verify that the assistant behaves as expected and that the correct documents are being retrieved.
Debugging poor responses: When users report that the AI gave an incorrect or unhelpful answer, administrators can inspect the exchange to understand whether the issue was caused by a missing document, an incorrect prompt, insufficient context, or a model limitation.
Token usage monitoring: The inspector shows token counts for requests and responses, and what the tools of each exchange cost, helping administrators understand the cost and efficiency of their assistant configurations.
RAG verification: By examining the request details, administrators can confirm that the embedding search is returning relevant document passages and that the context window is being used effectively.